Pattern: Extract, Then Reason
“Read this invoice and tell me whether to approve it” is two tasks pretending to be one. The model reads badly and reasons badly at the same time, in a single opaque step, and when the answer is wrong there is nothing to inspect. Splitting it produces an artefact in the middle, and the artefact is most of the benefit. One call doing two jobs The combined prompt is the natural first draft because…
The combined prompt of reading an invoice and making an approval decision in a single step presents several issues. This fused call hides two error rates, making it difficult to determine whether a wrong answer stems from a reading error or a reasoning error. The untestable nature of the combined prompt means you cannot identify which factor is causing the problem. Splitting the tasks into two separate calls allows for easier testing and improvement of both the extraction and decision-making processes.
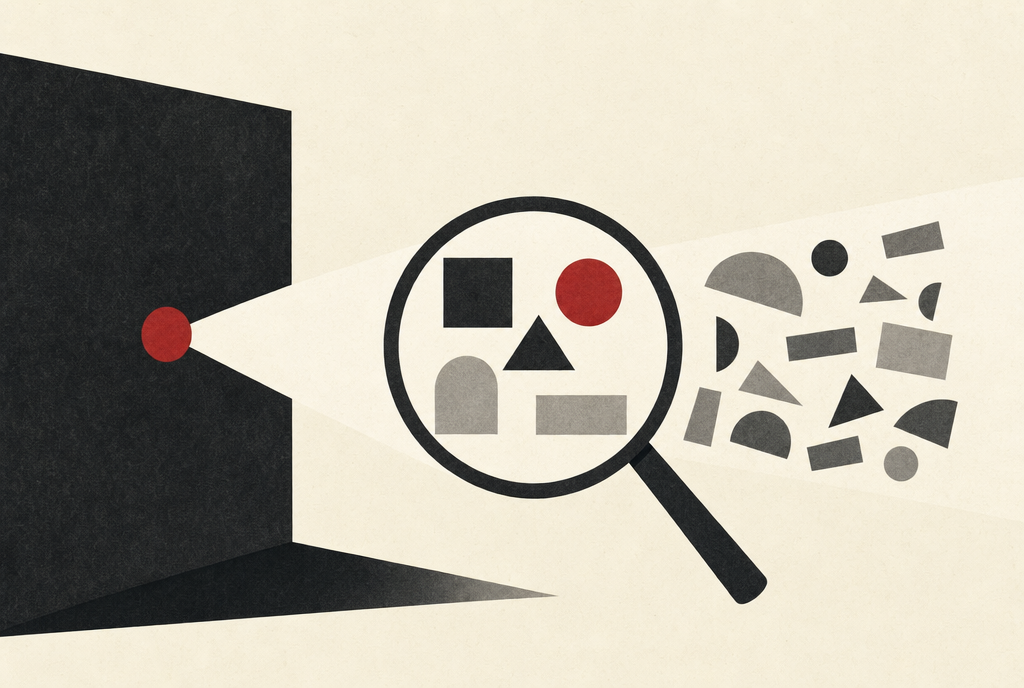
In the first stage, the extraction process reads the invoice and produces a structured output containing details such as vendor information, total amount, currency, line items, and PO number. Each extracted field includes a span indicating its location in the original document, enabling easy verification of the extracted values against the source.
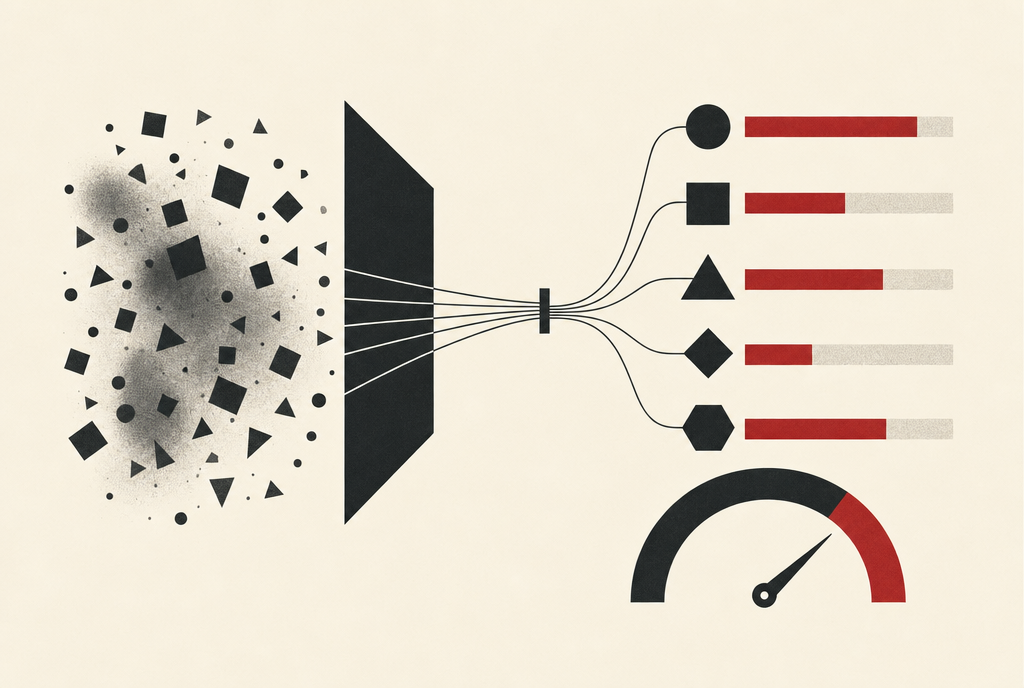
The second stage, the decision-making stage, takes the extracted information and applies the appropriate policy to determine the approval outcome. This stage operates on the structured data rather than the original document, minimizing the impact of any document formatting issues.
The key advantages of splitting the tasks include better observability, easier debugging, and the potential for separate improvements in each stage. By splitting the process, you can individually test and enhance the extraction accuracy and the reasoning given correct fields. If the extraction stage is weak, focusing on schema and formatting improvements may resolve the issues.
Conversely, if the reasoning stage given correct fields is weak, it may indicate that the policy logic needs refinement, or the model may not be the most suitable tool for the decision-making process.
To measure the effectiveness of splitting the tasks, a cheap experiment can be conducted by labeling a set of documents with both the extracted field values and the correct final decision. Running the fused version and the split version separately allows for comparing the accuracy of the final decisions and the field-level extraction accuracy.
By analyzing these two numbers, you can identify which stage contributes more to the overall accuracy and focus on the appropriate area for improvement. The split approach also enables the policy to be expressed as code, eliminating the need for additional model calls and providing a more deterministic and testable workflow.
Written by urgent.news from Dev.to's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.