Let the Compiler Argue With the Demo: A Repeatable C++ Grader for Coding Models
Benchmark screenshots are abundant. The narrower question a working C++ team needs answered is harsher: can a coding assistant repair the sort of defect that actually appears in our tree, under our warning policy, without smearing edits across files that were off limits? I stopped asking for impressions and built a tiny grader that turns each model answer into the same three artifacts: a strict…
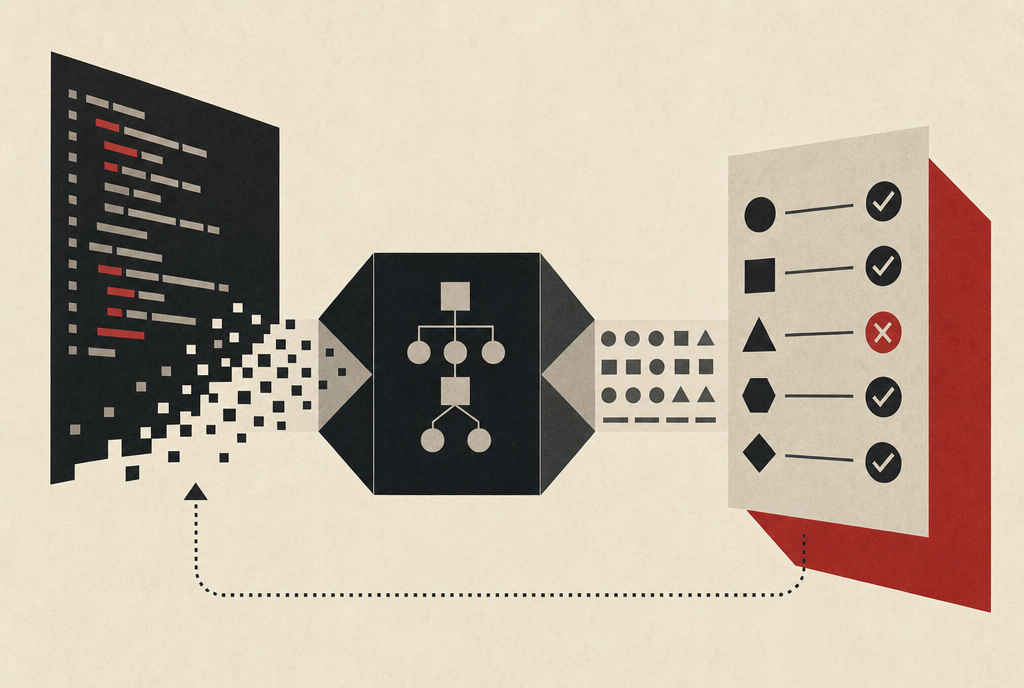
A C++ grader has been developed to evaluate coding models' performance in addressing coding defects. This tool follows a strict set of three gates: build, behavior, and scope. The build gate checks if the code compiles using the same compiler flags as the original project, including warnings as errors and sanitizers. The behavior gate ensures the code matches the expected output, without referencing any information the model was not given during testing.
The scope gate verifies that the proposed solution stays within the specified boundaries, without altering unrelated files.
The grader operates by reading a JSONL file containing model labels, task directories, and source files. It then generates a verdict for each candidate. The grader itself is simple and can be easily adapted to work with different models or datasets. To test its functionality, a sliding-window sums task was used. The model is provided with a buggy version of the code and asked to fix the defect without changing the interface or adding dependencies.
The hidden side of the task consists of an expected output file and a build configuration with specific flags and sanitizers. Successful candidates adjust the inner bound, handle edge cases, and pass both the output comparison and sanitizer checks.
Written by urgent.news from Dev.to's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.