I'm running AI on my NAS at 5 tokens per second, and it's surprisingly useful
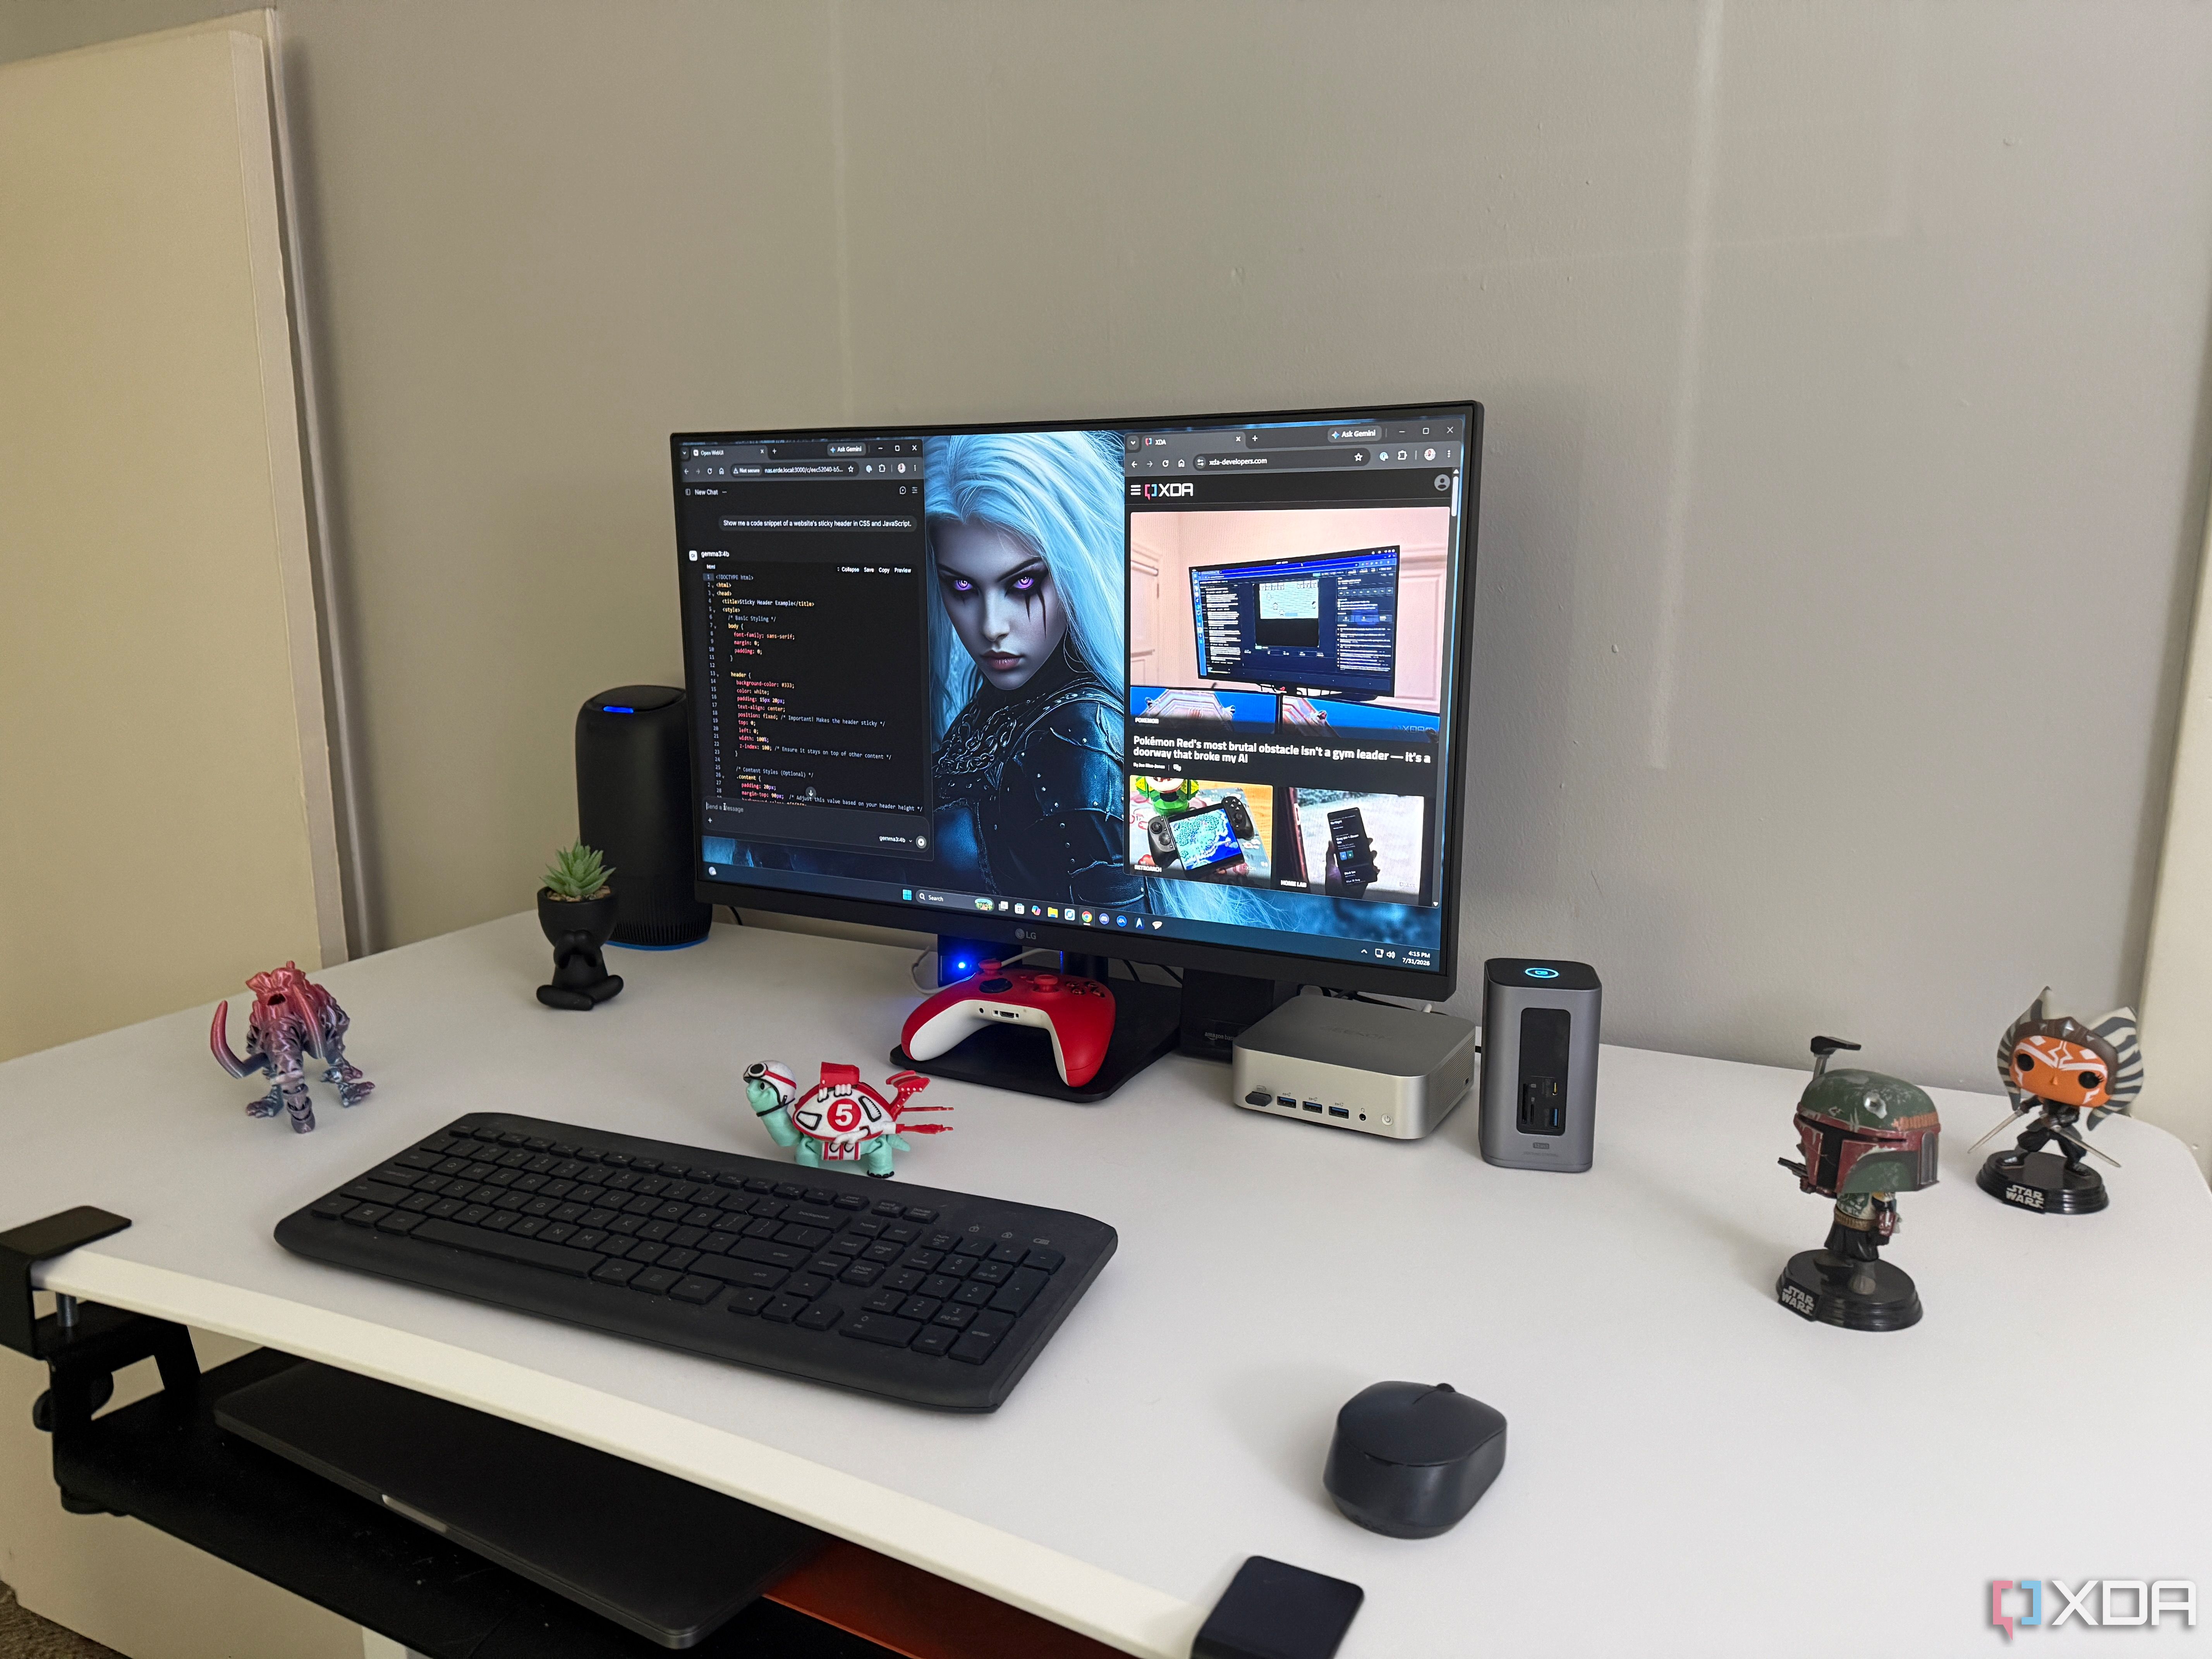
I ran a local AI model on my NAS with no GPU at about 5 tokens per second. It’s painfully slow, but far more useful than I expected.
We haven't written up this one. XDA Developers has the full story — the link below goes straight to it.